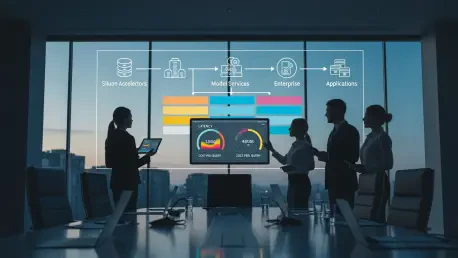
Lead: A Sharper Question About AI Scale Budgets shifted, data maps sprawled, and a tougher question cut through the noise: who truly commands AI at enterprise scale when chips, models, data, and power constraints collide in the same boardroom conversation? On stage at Next, Google Cloud offered an
Boardrooms are louder now as AI PC pilots give way to rollouts that promise faster work, lower latency, and tighter data control while forcing hard choices on budgets, skills, and governance. That shift has pushed the conversation from curiosity to execution: who gains, how fast, and at what cost.
Trading desks and risk teams kept hitting a wall: petabyte-scale data pipelines ballooned cloud bills while overnight jobs crept into trading hours, and a single ad hoc query could idle analysts for minutes as CSVs slogged across object storage. That bottleneck framed the appeal of Delta Parquet,
Regulators did not wait for collaboration vendors to catch up, and UK enterprises with cross-border exposure increasingly demanded unambiguous proof that meeting recordings, chat logs, call metadata, and AI outputs stayed within national boundaries. That pressure culminated in a notable change:
The instantaneous nature of modern software development has collided with a powerful new reality where artificial intelligence can scan millions of lines of code in seconds to find deep-seated security flaws. This shift marks a departure from the days when finding a significant zero-day
The transition from a world where humans painstakingly type every line of code to one where three-quarters of a global tech giant’s software is generated by artificial intelligence marks a definitive boundary in industrial history. This shift is not a distant prediction but a present reality at